CHRIS MARTINEZ · HOMELAB
WELCOME
The room is dark. Power it on to look around.
Hi, I'm Chris. I love playing with tech, and these days that means running two self-hosted Linux servers at home and looking for IT work.
You'll need this! Use it to chat with me about Chris!
Sage only knows what Chris told her. Chats are saved so Chris can read them.
LOAD SAVE
My projects
Six saves, oldest first. Open one to see what it is and its quest log: what broke, why, and how I fixed it.
SLOT 1AI WorkstationJUL 2026 · 3 QUESTS
A gaming laptop (Ryzen 9, Radeon RX 6800M) running Nobara Linux as a 24/7 AI server: a local chat model, AI memory and an image pipeline.
- Nobara Linux
- systemd
- llama.cpp
- Vulkan
QUEST LOG
▸ Laptop kept shutting itself off
- SYMPTOM
- Hard power-offs on three separate days. The kernel log showed the GPU tripping its over-temperature cutoff.
- CAUSE
- Three AI models kept the GPU busy around the clock while the power profile was pinned to performance.
- FIX
- Balanced power profile, a timer that unloads idle models, and a guard that pauses services at 85 °C.
- VERIFIED
- Caught a live spike at 94 °C and recovered. Zero over-temperature events in six weeks of logs.
▸ Two models fighting over 12 GB of VRAM
- SYMPTOM
- VRAM at 12.8 of 12.9 GB and the chat model crawling at 2 tokens per second.
- CAUSE
- A helper that pauses one model during image jobs restarted it afterward, even when I had shut it off on purpose.
- FIX
- It now restores only the services it paused itself.
- VERIFIED
- Image job ran, the chat model paused and came back on its own, no overlap.
▸ Chat model fell back to the CPU after a kernel upgrade
- SYMPTOM
- 7 tokens per second instead of about 45, with almost nothing loaded on the GPU.
- CAUSE
- A boot race. On the new kernel the GPU finishes initializing a few seconds after the model starts.
- FIX
- A pre-start check that waits until the GPU is visible before the model loads.
- VERIFIED
- Three clean reboots, 49 to 54 tokens per second.
SLOT 2AI MemorySEP 2026 · 2 QUESTS
Long-term memory for my AI assistants: Honcho on PostgreSQL, with a small model on the CPU turning conversations into facts.
- Honcho
- PostgreSQL
- Redis
- Podman
- Python
QUEST LOG
▸ Memory recorded my assistant's words as mine
- SYMPTOM
- Stored facts about me that I never said, and per-message recall that never fired.
- CAUSE
- The small model writing memories mixed up speakers, and a hook was reading the wrong field name.
- FIX
- A filtering proxy that checks each fact against both speakers' sentences, plus the hook fix.
- VERIFIED
- 76 facts kept, 53 rejected, every decision logged for audit.
▸ Automated runs were saved as if I said them
- SYMPTOM
- A design tool's automated AI runs showed up in my memory as my own messages.
- CAUSE
- The memory hooks couldn't tell me apart from scripts.
- FIX
- Hooks now skip any run that identifies itself as automated, and I deleted the junk entries.
- VERIFIED
- An automated test run saved nothing; normal chats still recall fine.
SLOT 3Art PipelineSEP 2026 · 2 QUESTS
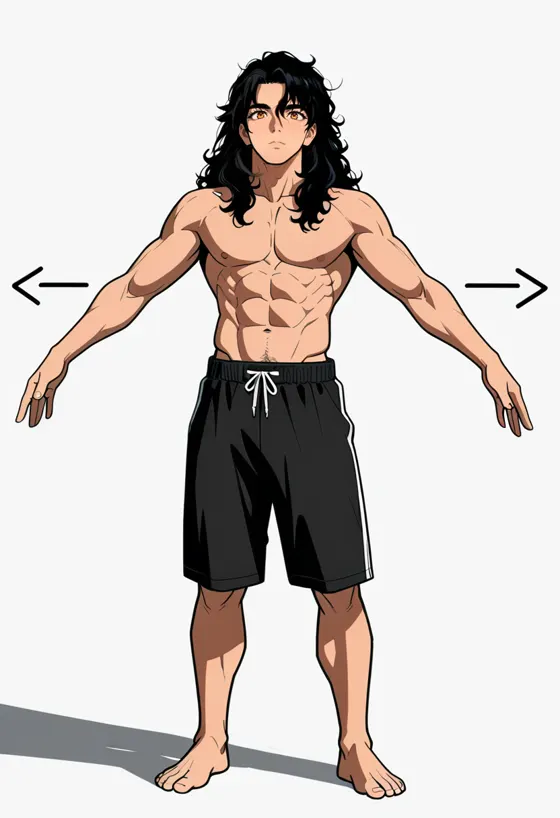
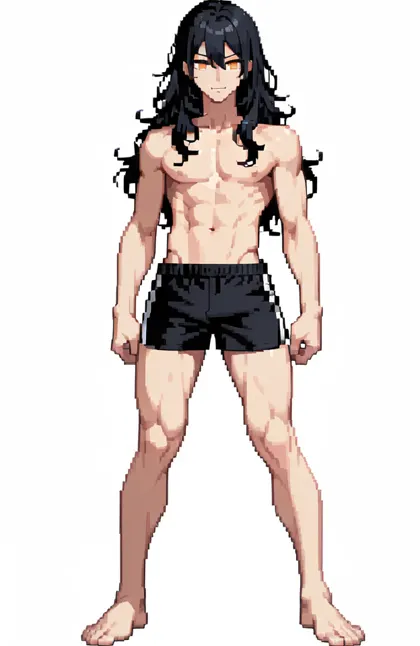
Local image generation for my game's sprites: SDXL with pose control and a pixel-art LoRA, all on my own GPU.
- ComfyUI
- SDXL
- ControlNet
- Python
QUEST LOG
▸ Image pipeline froze the whole system
- SYMPTOM
- The second image in every batch hung. RAM sat at 28 of 30 GB with over 20 GB in swap.
- CAUSE
- Each image went in as its own job, and the 7 GB model reloaded every time without freeing the old copy.
- FIX
- Rewrote the batch script to send every image as one job, so models load once.
- VERIFIED
- Six images in one run with RAM stable.
▸ From stiff rigs to pixel sprites
- GOAL
- Game art that looks hand-made, not like a puppet rig.
- TRIED
- A skeleton rig first, then frame-by-frame runs guided by pose maps.
- RESULT
- Switched to a pixel-art LoRA for small overworld sprites, keeping the big art for battles.
SLOT 4Home ServerOCT 2026 · 5 QUESTS
A 2016 Dell laptop I wiped and rebuilt as a headless Ubuntu Server. Lid closed, running 24/7 in the corner.
- Ubuntu Server
- NVIDIA + CUDA
- systemd
- AdGuard Home
QUEST LOG
▸ Wipe and rebuild
- GOAL
- Turn an old laptop into a quiet, always-on server.
- DID
- Ubuntu Server, lid-close and sleep disabled, NVIDIA drivers, and an AI runtime compiled from source (CUDA 12.4 needed an older compiler).
- VERIFIED
- A small AI model starts on boot and survives reboots.
▸ New server stuck at 800 MHz
- SYMPTOM
- Builds crawled. The CPU never left its 800 MHz floor and the battery said "not charging".
- CAUSE
- A low-wattage charger. The firmware saw too little power and throttled the CPU to its minimum.
- FIX
- Swapped in the correct 130 W charger.
- VERIFIED
- CPU back up to about 2.9 GHz under load.
▸ Picking the right GPU backend
- GOAL
- Get the most out of an old 4 GB GPU.
- TESTED
- Built and benchmarked two backends, CUDA and Vulkan, on the same model.
- RESULT
- CUDA read prompts almost 5x faster (73 vs 16 tokens per second), so CUDA stayed.
▸ Its own heat guard
- GOAL
- Keep a ten-year-old laptop from cooking itself.
- DID
- A timer checks temperatures every 15 seconds, pauses the AI at 85 °C GPU or 92 °C CPU, and resumes below 75 °C.
- VERIFIED
- Tested by forcing a trip; it paused and resumed on its own.
▸ Network ad and scam blocker
- GOAL
- Block ads, trackers and known-malicious domains for the whole house.
- DID
- AdGuard Home with security blocklists and encrypted upstream DNS.
- STATUS
- Blocking ad domains in tests; house-wide rollout is next.
SLOT 5Private ChatOCT 2026 · 4 QUESTS
My own Matrix chat server on the home server, with a pixel-art web app on my phone. My AI assistant lives there. Only reachable over my private Tailscale network.
- Matrix
- Cinny
- Tailscale
- Python
QUEST LOG
▸ Moving chat off the gaming laptop
- GOAL
- Run chat on the always-on server instead of the gaming rig.
- DID
- Fresh server and accounts, registration locked, old server backed up and retired.
- VERIFIED
- Phone app and AI assistant both moved over.
▸ Making it feel like a game
- GOAL
- A chat app that matches the rest of my world.
- DID
- A script that re-themes the stock web app: dusk palette, pixel font, fireflies, custom app icon, and RPG icons (a sword for pins, a monocle for search, a slime for emoji).
- VERIFIED
- Re-runs safely after app updates.
▸ My AI assistant forgot me after the move
- SYMPTOM
- On the new server it guessed at facts it used to know, like my own GPU.
- CAUSE
- Its memory was filed under my old chat app's user ID. On the new server I showed up as a new user with no history.
- FIX
- Mapped my new ID to the old one, so both open the same memory.
- VERIFIED
- A new message saved under the right identity, and recall returned its old memories.
▸ A public link broke my private chat
- SYMPTOM
- After I published a page from the server, my phone couldn't connect to chat: "couldn't establish a secure connection".
- CAUSE
- Publishing made the server's name resolve publicly, so my phone stopped using the private network.
- FIX
- Took the public page down; public things now live on separate hosting.
- VERIFIED
- Chat back within the hour, and the rule is written down.
SLOT 6This WebsiteOCT 2026 · 2 QUESTS
The site you're on: a pixel-art game on Cloudflare Pages, plus Sage, an AI guide running on my home server.
- HTML/CSS/JS
- Cloudflare Pages
- Cloudflare Tunnel
- Python
QUEST LOG
▸ Letting strangers talk to my home server, safely
- GOAL
- Recruiters can chat with an AI on my home server without opening my network.
- DID
- A tunnel that forwards only the chat API; a gatekeeper that checks access codes, rate-limits, and locks out guessers; a sandbox that cut its systemd exposure score from 6.4 to 1.1.
- VERIFIED
- Probing any other path returns 404, fake codes are rejected, and my home network stays private.
▸ Domain day
- SYMPTOM
- A brand-new domain was stuck on a locked registrar placeholder, so the site couldn't attach to it.
- FIX
- Served the site on www and added a permanent redirect from the bare domain.
- VERIFIED
- Both addresses load over HTTPS with a valid certificate.
OPTIONS
My setup
WHAT'S RUNNING
- Local chat modelRUNNING
Gemma 4 12B on the GPU, about 49 tokens per second.
- AI memoryRUNNING
Honcho on PostgreSQL, with a filter I wrote that drops facts credited to the wrong speaker.
- Home serverRUNNING
A 2016 Dell I wiped and rebuilt on Ubuntu Server, with NVIDIA drivers, CUDA and its own heat guard.
- Private chat serverRUNNING
Matrix on the home server, with a pixel-themed web app on my phone. My AI assistant lives there, reachable only over Tailscale.
- Thermal guardRUNNING
Pauses heavy jobs at 85 °C junction temperature and resumes them below 75 °C.
- Art pipelineON DEMAND
ComfyUI with SDXL, pose control and a pixel-art LoRA, for game sprites.
MACHINE 1 · AI WORKSTATION
- System
- ASUS ROG Strix G15 laptop
- CPU
- Ryzen 9 5900HX, 8 cores
- GPU
- Radeon RX 6800M, 12 GB
- Memory
- 32 GB
- OS
- Nobara Linux (Fedora 44)
- Network
- Tailscale private network
- Power profile
- Balanced
MACHINE 2 · HOME SERVER
- System
- Dell Inspiron 15 7559 (2016)
- GPU
- GeForce GTX 960M, 4 GB
- OS
- Ubuntu Server LTS
- Runs
- Matrix chat server, a small AI model
- Mode
- Lid closed, headless, 24/7
SKILLS
- Linux
- systemd
- journalctl
- Troubleshooting
- Networking
- Tailscale
- Ubuntu Server
- NVIDIA / CUDA
- PostgreSQL
- Podman
- Self-hosted AI
- Godot
EXTRAS
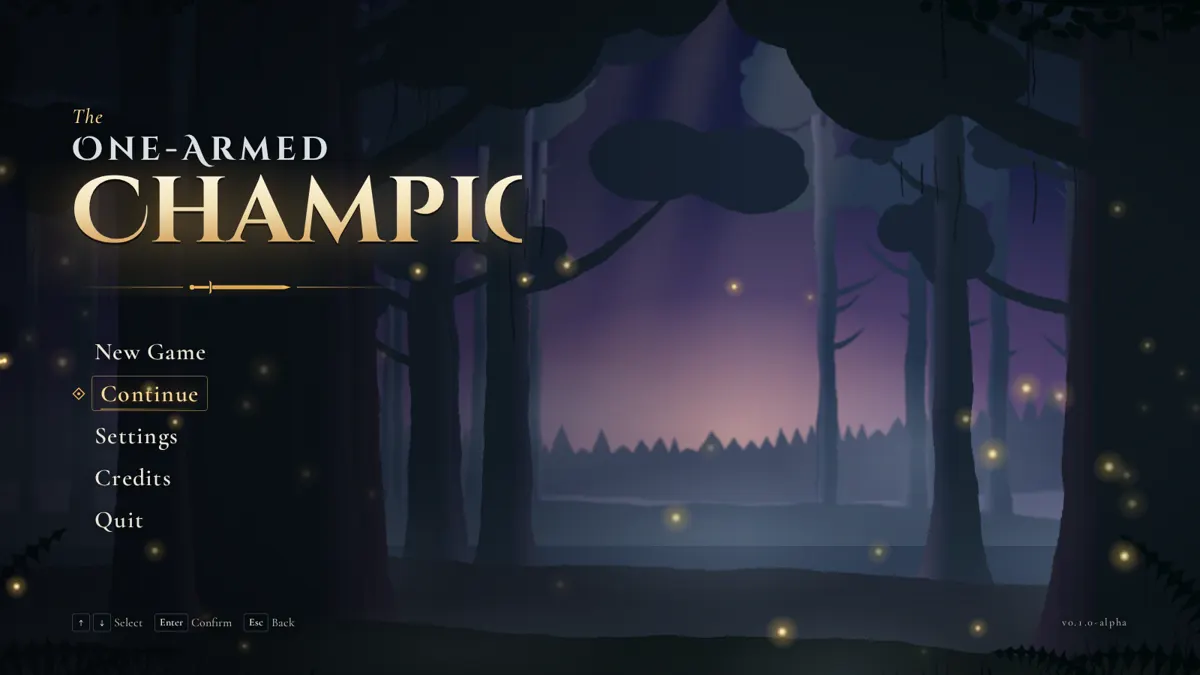
The One-Armed Champion
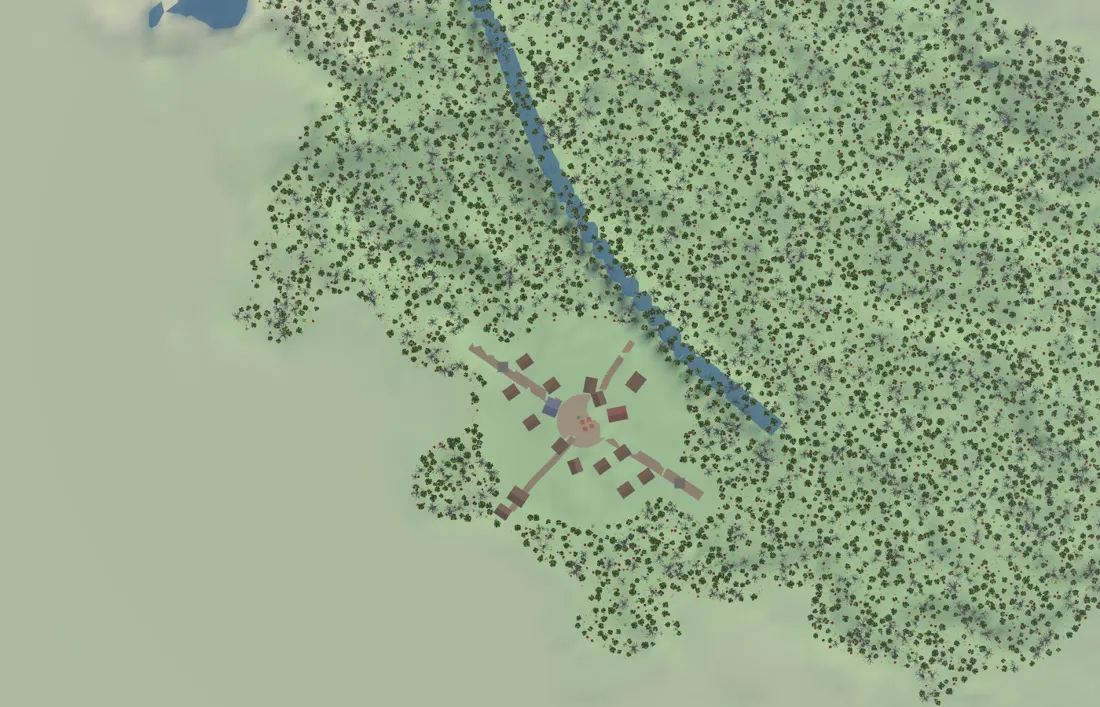
A 2D action RPG I'm building in Godot. It's where I practice procedural generation, art pipelines and automated testing.
- Godot 4
- 20,919 placed objects
- 32 m streaming chunks
- 15 automated tests
CREDITS
How this was made
Designed, run and verified by Chris Martinez. AI coding agents did much of the typing. Every fix listed here was checked on the real machine.
Type: Press Start 2P and IBM Plex Mono.
Last updated October 2026.